 DBLP
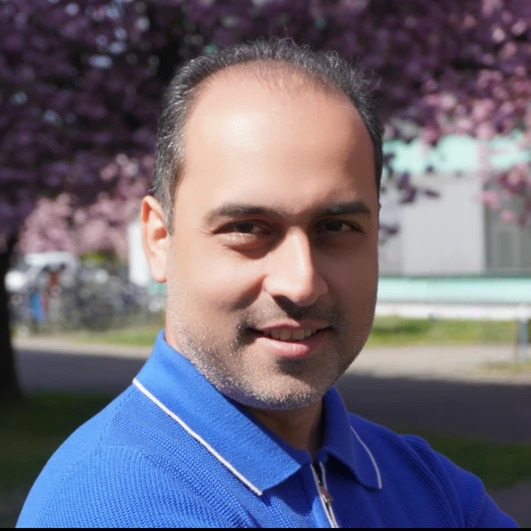
Kazem Shekofteh, Dr.
Kazem Shekofteh is a postdoctoral researcher at the Institute of Computer Engineering (ZITI), Heidelberg University, where he has been teaching since 2022. His research focuses on GPU computing, performance analysis of parallel programs, and high-performance computing for bioinformatics, with growing interest in emerging accelerators such as Tenstorrent and Graphcore IPUs. He received his PhD (2019) and MSc from Ferdowsi University of Mashhad, Iran, and previously held an assistant professorship at Shandiz Institute of Higher Education. He was a visiting scholar at Heidelberg University in late 2016, and his work has appeared in leading journals such as IEEE Transactions on Parallel and Distributed Systems. At Heidelberg he lectures on GPU Computing, Consistency and Coherence, and the Advanced Seminar. In 2026 he received a heiSKILLS Fellowship “KI in der Lehre (AI in Teaching)” for an AI-powered personalized assignment system.
Research Interests
- Performance — characterization and analysis of parallel programs on GPUs and accelerators
- Emerging hardware — algorithm design for Tenstorrent and Graphcore IPU
- Parallel computing challenges — irregularity and sparsity
- Applications — bioinformatics on accelerators
Awards & Fellowships
- 2026 — heiSKILLS Fellowship “KI in der Lehre (AI in Teaching)”, Heidelberg University, for AI-Powered Personalized Assignment System.
Recent Service (last 4 years)
Co-Organizer
- 2026 — Workshop on IoT, Edge, and Mobile for Embedded Machine Learning (ITEM), Naples, Italy, September 11.
Co-Chair
- 2024 — ITEM Workshop, Vilnius, Lithuania, September 9.
- 2023 — ITEM Workshop, Torino, Italy, September 18.
- 2022 — ITEM Workshop, Grenoble, France, September 19.
Program Committee Member
- ACM ICPP — 55th (2026, Singapore); 54th (2025, USA); 53rd (2024, Sweden); 52nd (2023, USA)
- IEEE Euro-Par — 32nd (2026, Italy); 31st (2025, Germany); 30th (2024, Spain)
- PMBS Workshop @ IEEE/ACM SC — 17th (2026, USA); 16th (2025, USA); 15th (2024, USA)
- IEEE IPDPS — 39th (2025, Italy)
- ACM Computing Frontiers (CF) — 23rd (2026, Italy)
- GCA Workshop @ CANDAR — 2023, 2024, 2025, Japan
- IEEE/ACM ICCD — 42nd (2024, Italy)
- IEEE/ACM Supercomputing (SC) — 2023, USA
- IEEE/ACM CCGrid — 23rd (2023, India)
Poster Committee Member
- 2023 — IEEE/ACM Supercomputing (SC)
Student Volunteer Co-Chair
- 2026 — 39th IEEE International System-on-Chip Conference (SoCC)
- 2022 — IEEE International Conference on Cluster Computing (CLUSTER)
Reviewer
Journals
- IEEE Transactions on Parallel and Distributed Systems (TPDS)
- ACM Transactions on Programming Languages and Systems (TOPLAS)
- ACM Transactions on Architecture and Code Optimization (TACO)
- Elsevier — Journal of Parallel and Distributed Computing (JPDC)
- Elsevier — Future Generation Computer Systems (FGCS)
- Springer — The Journal of Supercomputing
Conferences
- ACM CF (2025); IEEE Cluster (2023, 2024); IEEE/ACM ICCAD (2024); ACM ICS (2024); ICCKE (2014–2024)
Publications
- Parameter Savings Are Not Memory Savings: Butterfly Attention on a Tile Processor24th International Workshop on Algorithms, Models and Tools for Parallel Computing on Heterogeneous Platforms (HeteroPar 2026) , collocated with Euro-PAR (accepted for publication), 2026
@inproceedings{HeteroPar2026PhilippKazem, title = {Parameter Savings Are Not Memory Savings: Butterfly Attention on a Tile Processor}, author = {Hematty, Philipp and Shekofteh, S.-Kazem and Fr{{\"o}}ning, Holger}, booktitle = {24th International Workshop on Algorithms, Models and Tools for Parallel Computing on Heterogeneous Platforms (HeteroPar 2026) , collocated with Euro-PAR (accepted for publication)}, year = {2026}, url = {https://eventi.unibo.it/heteropar2026} } - Characterizing Needleman-Wunsch Sequence Alignment on the Graphcore IPU: Memory Trade-offs and Optimization Strategies32nd International European Conference on Parallel and Distributed Computing (Euro-PAR) (accepted for publication) (Euro-PAR), 2026
@inproceedings{EuroPAR2026ipu, title = {Characterizing Needleman-Wunsch Sequence Alignment on the Graphcore IPU: Memory Trade-offs and Optimization Strategies}, author = {Shekofteh, S.-Kazem and Kochendörfer, Nils and Fr{{\"o}}ning, Holger}, booktitle = {32nd International European Conference on Parallel and Distributed Computing (Euro-PAR) (accepted for publication)}, series = {Euro-PAR}, year = {2026}, url = {https://2026.euro-par.org/program/main-conference} } - Are IPUs Viable for Genomic Sequence Alignment? Performance and Memory AnalysisWorkshop Biosignale 2026, Innsbruck, Austria, 2026
@inproceedings{Biosignale2026Kazem, title = {Are IPUs Viable for Genomic Sequence Alignment? Performance and Memory Analysis}, author = {Shekofteh, S.-Kazem and Kochendörfer, Nils and Fr{{\"o}}ning, Holger}, booktitle = {Workshop Biosignale 2026, Innsbruck, Austria}, year = {2026}, url = {https://doi.org/10.15203/99106-194-6-21}, } - Comparative Benchmark of Scaled-YOLOv4 on Graphcore IPU and NVIDIA GPU19th Workshop on Design and Architectures for Signal and Image Processing (DASIP 2026), collocated with HiPEAC Conference, 2026
@inproceedings{DASIP26ArjanKazem, title = {Comparative Benchmark of Scaled-YOLOv4 on Graphcore IPU and NVIDIA GPU}, author = {Siddhpura, Arjan and Shekofteh, S.-Kazem and Fr{{\"o}}ning, Holger}, booktitle = {19th Workshop on Design and Architectures for Signal and Image Processing (DASIP 2026), collocated with HiPEAC Conference}, year = {2026}, url = {https://link.springer.com/chapter/10.1007/978-3-032-23871-9_9} } - Butterfly factorization for vision transformers on multi-IPU systemsParallel Computing, 127, 103165, 2026
@article{SHEKOFTEH2026103165, title = {Butterfly factorization for vision transformers on multi-IPU systems}, journal = {Parallel Computing}, volume = {127}, pages = {103165}, year = {2026}, issn = {0167-8191}, doi = {https://doi.org/10.1016/j.parco.2025.103165}, url = {https://www.sciencedirect.com/science/article/pii/S0167819125000419}, author = {Shekofteh, S.-Kazem and Bogacz, Daniel and Alles, Christian and Fr{{\"o}}ning, Holger}, keywords = {Intelligence processing units, Butterfly factorization, Vision transformer, Machine learning, Model compression} } - Reducing Memory Requirements for the IPU using Butterfly FactorizationsSC ’23 Workshops of The International Conference on High Performance Computing, Network, Storage, and Analysis, SC-W 2023, Denver, CO, USA, November 12-17, 2023, 1255–1263, ACM, 2023
@inproceedings{DBLP:conf/sc/ShekoftehAF23, author = {Shekofteh, S.-Kazem and Alles, Christian and Fr{\"{o}}ning, Holger}, title = {Reducing Memory Requirements for the {IPU} using Butterfly Factorizations}, booktitle = {{SC} '23 Workshops of The International Conference on High Performance Computing, Network, Storage, and Analysis, {SC-W} 2023, Denver, CO, USA, November 12-17, 2023}, pages = {1255--1263}, publisher = {{ACM}}, year = {2023}, url = {https://doi.org/10.1145/3624062.3624196}, doi = {10.1145/3624062.3624196}, timestamp = {Tue, 28 Nov 2023 00:00:00 +0100}, } - On Performance Analysis of Graphcore IPUs: Analyzing Squared and Skewed Matrix MultiplicationCoRR, abs/2310.00256, 2023
@article{DBLP:journals/corr/abs-2310-00256, author = {Shekofteh, S.-Kazem and Alles, Christian and Kochend{\"{o}}rfer, Nils and Fr{\"{o}}ning, Holger}, title = {On Performance Analysis of Graphcore IPUs: Analyzing Squared and Skewed Matrix Multiplication}, journal = {CoRR}, volume = {abs/2310.00256}, year = {2023}, url = {https://arxiv.org/abs/2310.00256}, doi = {10.48550/ARXIV.2310.00256}, eprinttype = {arXiv}, eprint = {2310.00256}, timestamp = {Wed, 18 Oct 2023 01:00:00 +0200}, } - cCUDA: Effective Co-Scheduling of Concurrent Kernels on GPUsIEEE Trans. Parallel Distributed Syst., 31(4), 766–778, 2020
@article{DBLP:journals/tpds/ShekoftehNNFY20, author = {Shekofteh, S.-Kazem and Noori, Hamid and Naghibzadeh, Mahmoud and Fr{\"{o}}ning, Holger and Yazdi, Hadi Sadoghi}, title = {cCUDA: Effective Co-Scheduling of Concurrent Kernels on GPUs}, journal = {{IEEE} Trans. Parallel Distributed Syst.}, volume = {31}, number = {4}, pages = {766--778}, year = {2020}, url = {https://doi.org/10.1109/TPDS.2019.2944602}, doi = {10.1109/TPDS.2019.2944602}, timestamp = {Fri, 02 Oct 2020 01:00:00 +0200}, } - Metric Selection for GPU Kernel ClassificationACM Trans. Archit. Code Optim., 15(4), 68:1–68:27, 2019
@article{DBLP:journals/taco/ShekoftehNNYF19,
  author = {Shekofteh, S.-Kazem and Noori, Hamid and Naghibzadeh, Mahmoud and Yazdi, Hadi Sadoghi and Fr{\"{o}}ning, Holger},
  title = {Metric Selection for {GPU} Kernel Classification},
  journal = {{ACM} Trans. Archit. Code Optim.},
  volume = {15},
  number = {4},
  pages = {68:1--68:27},
  year = {2019},
  url = {https://doi.org/10.1145/3295690},
  doi = {10.1145/3295690},
  timestamp = {Sat, 08 Jan 2022 00:00:00 +0100},
}
- Efficient scheduling of streams on GPGPUsThe Journal of Supercomputing, 76(11), 9270–9302, 2020
@article{roui2020efficient, author = {Beheshti Roui, Mohamad and Shekofteh, S.-Kazem and Noori, Hamid and Harati, Ahad}, date = {2020/11/01}, date-added = {2024-04-04 16:55:55 +0200}, date-modified = {2024-04-04 16:56:58 +0200}, doi = {10.1007/s11227-020-03209-x}, id = {Beheshti Roui2020}, isbn = {1573-0484}, journal = {The Journal of Supercomputing}, number = {11}, pages = {9270--9302}, title = {Efficient scheduling of streams on GPGPUs}, url = {https://doi.org/10.1007/s11227-020-03209-x}, volume = {76}, year = {2020}, bdsk-url-1 = {https://doi.org/10.1007/s11227-020-03209-x} } - Predicting Execution Time of CUDA Kernels with Unified Memory Capability2019 9th International Conference on Computer and Knowledge Engineering (ICCKE), 2019 9th International Conference on Computer and Knowledge Engineering (ICCKE), 437–443, 2019
@proceedings{khorshahiyan2019predicting, author = {Khorshahiyan, F. and Shekofteh, S.-Kazem and Noori, H.}, booktitle = {2019 9th International Conference on Computer and Knowledge Engineering (ICCKE)}, date-added = {2024-04-04 16:57:38 +0200}, date-modified = {2024-04-04 16:58:19 +0200}, doi = {10.1109/ICCKE48569.2019.8964952}, isbn = {2643-279X}, journal = {2019 9th International Conference on Computer and Knowledge Engineering (ICCKE)}, journal1 = {2019 9th International Conference on Computer and Knowledge Engineering (ICCKE)}, pages = {437--443}, title = {Predicting Execution Time of CUDA Kernels with Unified Memory Capability}, year = {2019}, year1 = {24-25 Oct. 2019}, url = {https://doi.org/10.1109/ICCKE48569.2019.8964952} } - A load scheduler for SIP proxy servers: design, implementation and evaluation of a history weighted window approachInternational Journal of Communication Systems, 30(3), e2980, John Wiley & Sons, Ltd, 2017
@article{montazerolghaem2017load, author = {Montazerolghaem, Ahmadreza and Shekofteh, S.-Kazem and Yaghmaee, M. H. and Naghibzadeh, Mahmoud}, date = {2017/02/01}, date-added = {2024-04-04 17:00:11 +0200}, date-modified = {2024-04-04 17:00:43 +0200}, doi = {https://doi.org/10.1002/dac.2980}, isbn = {1074-5351}, journal = {International Journal of Communication Systems}, journal1 = {International Journal of Communication Systems}, journal2 = {International Journal of Communication Systems}, journal3 = {Int J Commun Syst}, keywords = {load balancer; scheduler; session initiation protocol; asterisk; overload}, month = {2024/04/04}, n2 = {Summary The widespread use of Session Initiation Protocol as a signalling protocol has created various challenges. An important one is that its throughput can be severely degraded when an overload happens in the proxy server because of several retransmissions from the user agent. One common approach to overcome this problem is ?load balancing?. A balancer needs to know the status of proxy servers, which are continuously gathered implicitly or explicitly. Implicit methods have averagely less overhead than explicit ones. This paper attempts to prevent throughput reduction by balancing the loads among available proxy servers properly using an implicit mechanism called History Weighted Average Response time. The proposed algorithm is robust because it incurs no extra processing to proxy servers. The novelty of the mechanism is making use of ?response time history? to estimate the load being currently processed on servers. By implementing in a real testbed, throughput and scalability are improved compared with an important state-of-the-art similar algorithm. This improvement stems from no need for modification in SIP protocol, easy implementation and application, simple computations for making decision and no need for extra feedback between servers and load balancer. Copyright ? 2015 John Wiley \& Sons, Ltd.}, number = {3}, pages = {e2980}, publisher = {John Wiley \& Sons, Ltd}, title = {A load scheduler for SIP proxy servers: design, implementation and evaluation of a history weighted window approach}, url = {https://doi.org/10.1002/dac.2980}, volume = {30}, year = {2017}, year1 = {2017}, } - A novel load scheduling for session initiation protocol networks2014 4th International Conference on Computer and Knowledge Engineering (ICCKE), 2014 4th International Conference on Computer and Knowledge Engineering (ICCKE), 509–514, 2014
@proceedings{montazerolghaem2014novel, author = {Montazerolghaem, A. and Shekofteh, S.-Kazem and Khojaste, G. and Naghibzadeh, M. and Yaghmaee-M, M. -H.}, booktitle = {2014 4th International Conference on Computer and Knowledge Engineering (ICCKE)}, date-added = {2024-04-04 17:01:42 +0200}, date-modified = {2024-04-04 17:01:53 +0200}, doi = {10.1109/ICCKE.2014.6993376}, journal = {2014 4th International Conference on Computer and Knowledge Engineering (ICCKE)}, journal1 = {2014 4th International Conference on Computer and Knowledge Engineering (ICCKE)}, pages = {509--514}, title = {A novel load scheduling for session initiation protocol networks}, year = {2014}, year1 = {29-30 Oct. 2014}, url = {https://doi.org/10.1109/ICCKE.2014.6993376} } - CoreIIScheduler: Scheduling Tasks in a Multi-core-Based Grid Using NSGA-II TechniqueIntelligent Informatics, 507–518, Springer Berlin Heidelberg, 2013
@proceedings{najmabad2013corell, address = {Berlin, Heidelberg}, author = {Najm Abad, Javad Mohebbi and Shekofteh, S.-Kazem and Tabatabaee, Hamid and Mehrnejad, Maryam}, booktitle = {Intelligent Informatics}, date = {2013//}, date-added = {2024-04-04 17:02:50 +0200}, date-modified = {2024-04-04 17:03:11 +0200}, editor = {Abraham, Ajith and Thampi, Sabu M}, id = {10.1007/978-3-642-32063-7{\_}54}, isbn = {978-3-642-32063-7}, pages = {507--518}, publisher = {Springer Berlin Heidelberg}, title = {CoreIIScheduler: Scheduling Tasks in a Multi-core-Based Grid Using NSGA-II Technique}, year = {2013}, url = {https://doi.org/10.1007/978-3-642-32063-7_54} } - Reducing cache contention in a multi-core processor via a scheduler2010 3rd International Conference on Advanced Computer Theory and Engineering(ICACTE), 6, V6-555-V6-558, 2010
@inproceedings{shekofteh2010reducing, author = {Shekofteh, S.-Kazem and Deldari, Hossein and Khalkhali, Maryam Baradaran}, booktitle = {2010 3rd International Conference on Advanced Computer Theory and Engineering(ICACTE)}, date-added = {2024-04-04 17:06:21 +0200}, date-modified = {2024-04-04 17:06:30 +0200}, doi = {10.1109/ICACTE.2010.5579213}, keywords = {component;multi-core architecture;resource contention;shared cache;thread scheduling}, pages = {V6-555-V6-558}, title = {Reducing cache contention in a multi-core processor via a scheduler}, volume = {6}, year = {2010}, url = {https://doi.org/10.1109/ICACTE.2010.5579213} } - Improving cluster computing performance based on job futurity prediction2010 3rd International Conference on Advanced Computer Theory and Engineering(ICACTE), 2010 3rd International Conference on Advanced Computer Theory and Engineering(ICACTE), 6, V6-303–V6-307, 2010
@proceedings{salami2010improving, author = {Salami, H. and Saadatfar, H. and Fard, Farhad Rahmani and Shekofteh, S.-Kazem and Deldari, H.}, booktitle = {2010 3rd International Conference on Advanced Computer Theory and Engineering(ICACTE)}, date-added = {2024-04-04 17:05:56 +0200}, date-modified = {2024-04-04 17:06:09 +0200}, doi = {10.1109/ICACTE.2010.5579820}, isbn = {2154-7505}, journal = {2010 3rd International Conference on Advanced Computer Theory and Engineering(ICACTE)}, journal1 = {2010 3rd International Conference on Advanced Computer Theory and Engineering(ICACTE)}, pages = {V6-303--V6-307}, title = {Improving cluster computing performance based on job futurity prediction}, vo = {6}, volume = {6}, year = {2010}, year1 = {20-22 Aug. 2010}, url = {https://doi.org/10.1109/ICACTE.2010.5579820} } - Exploiting fuzzy approximator to head pose estimationSignal Processing Algorithms, Architectures, Arrangements, and Applications SPA 2010, Signal Processing Algorithms, Architectures, Arrangements, and Applications SPA 2010, 68–72, 2010| bib
@proceedings{khalkhali2010exploiting, author = {-Khalkhali, M. Baradaran and Shekofteh, S.-Kazem and Toosizadeh, S. and -T, M. . -R. Akbarzadeh}, booktitle = {Signal Processing Algorithms, Architectures, Arrangements, and Applications SPA 2010}, date-added = {2024-04-04 17:04:59 +0200}, date-modified = {2024-04-04 17:05:17 +0200}, isbn = {2326-0319}, journal = {Signal Processing Algorithms, Architectures, Arrangements, and Applications SPA 2010}, journal1 = {Signal Processing Algorithms, Architectures, Arrangements, and Applications SPA 2010}, pages = {68--72}, title = {Exploiting fuzzy approximator to head pose estimation}, year = {2010}, year1 = {23-25 Sept. 2010} } - Head pose estimation using fuzzy approximator augmented by redundant membership functions2010 2nd International Conference on Software Technology and Engineering, 2010 2nd International Conference on Software Technology and Engineering, 2, V2-306–V2-310, 2010
@proceedings{shekofteh2010head, author = {Shekofteh, S.-Kazem and Baradaran-K, M. and Toosizadeh, S. and Akbarzadeh-T, M. -R. and Hashemi, M.}, booktitle = {2010 2nd International Conference on Software Technology and Engineering}, date-added = {2024-04-04 17:03:53 +0200}, date-modified = {2024-04-04 17:04:03 +0200}, doi = {10.1109/ICSTE.2010.5608799}, journal = {2010 2nd International Conference on Software Technology and Engineering}, journal1 = {2010 2nd International Conference on Software Technology and Engineering}, pages = {V2-306--V2-310}, title = {Head pose estimation using fuzzy approximator augmented by redundant membership functions}, vo = {2}, volume = {2}, year = {2010}, year1 = {3-5 Oct. 2010}, url = {https://doi.org/10.1109/ICSTE.2010.5608799} } - A fuzzy approximator with Gaussian membership functions to estimate a human’s head pose2010 10th International Conference on Intelligent Systems Design and Applications, 2010 10th International Conference on Intelligent Systems Design and Applications, 1154–1158, 2010
@proceedings{baradaran2010fuzzy,
  author = {Baradaran-K, M. and Shekofteh, S.-Kazem and Toosizadeh, S. and Akbarzadeh-T, M. -R.},
  booktitle = {2010 10th International Conference on Intelligent Systems Design and Applications},
  date-added = {2024-04-04 17:03:24 +0200},
  date-modified = {2024-04-04 17:03:34 +0200},
  doi = {10.1109/ISDA.2010.5687029},
  isbn = {2164-7151},
  journal = {2010 10th International Conference on Intelligent Systems Design and Applications},
  journal1 = {2010 10th International Conference on Intelligent Systems Design and Applications},
  pages = {1154--1158},
  title = {A fuzzy approximator with Gaussian membership functions to estimate a human's head pose},
  year = {2010},
  year1 = {29 Nov.-1 Dec. 2010},
  url = {https://doi.org/10.1109/ISDA.2010.5687029}
}